Design · July 31, 2026
Your Design System Dashboard Is Lying to You — Why Observability Is What You Actually Need
By Hailey Armstrong · Principal UX Designer
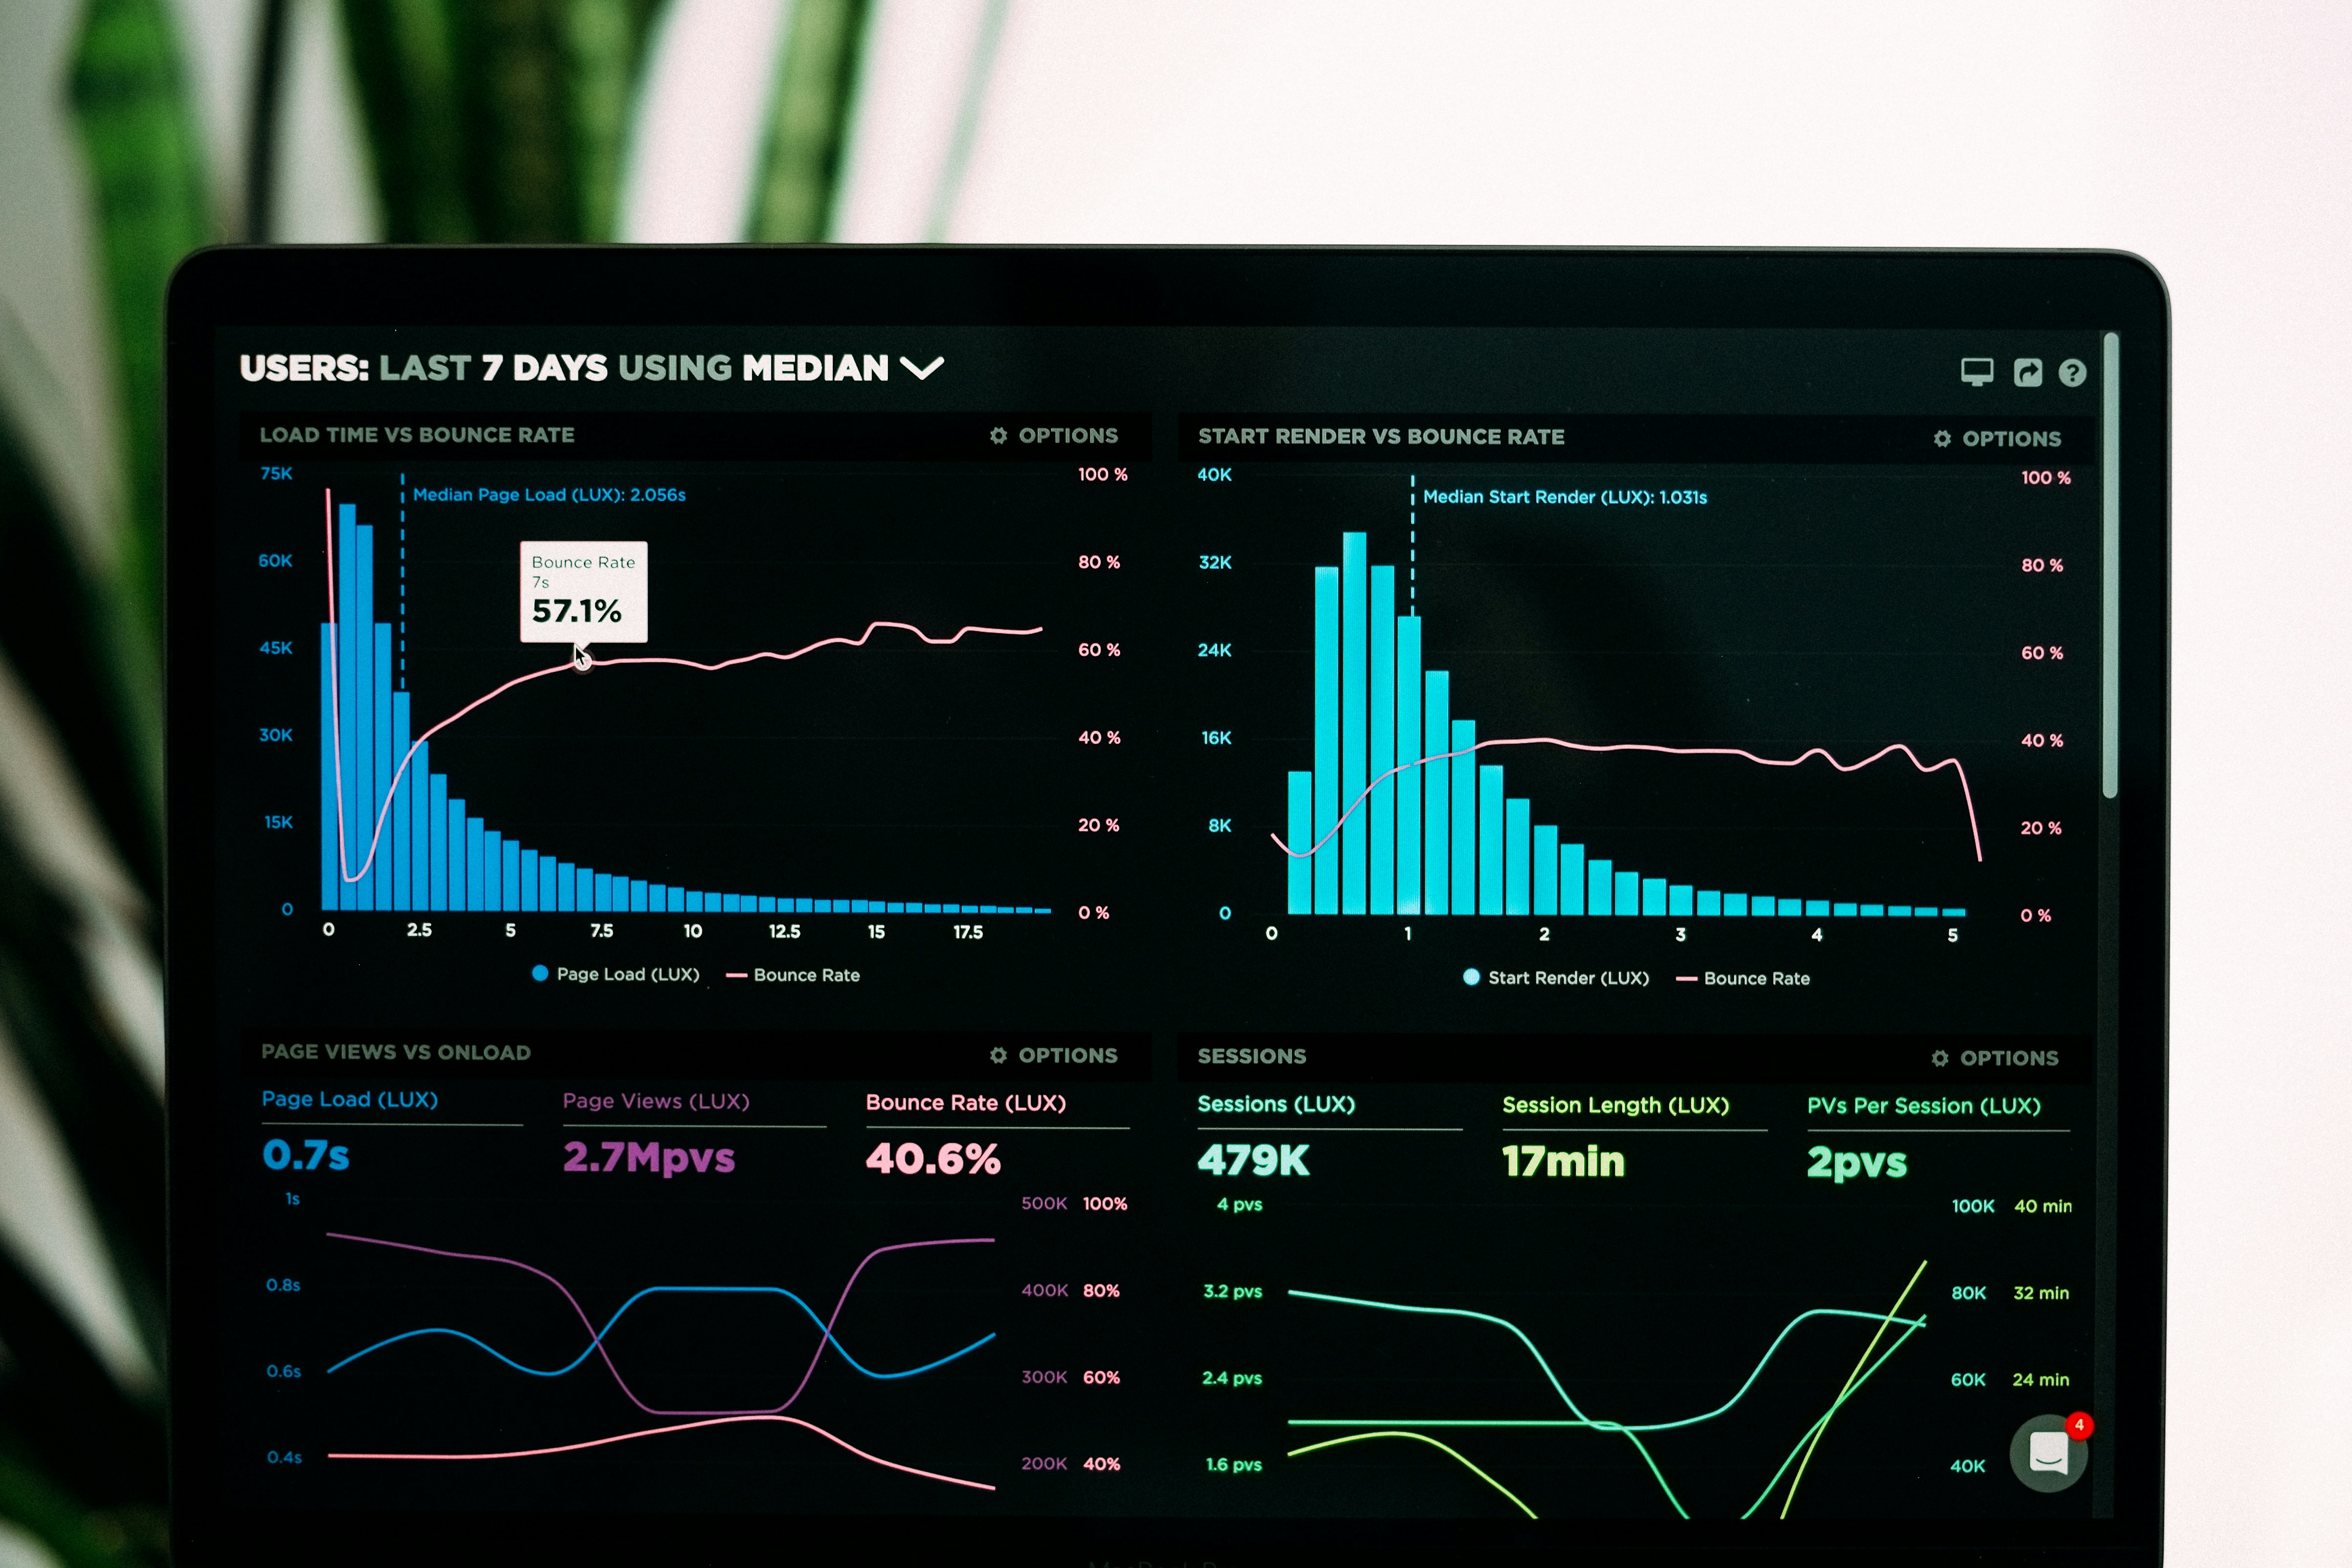
Photo by Luke Chesser on Unsplash
4,200 Instances, 600 Overridden
Your design system dashboard reports that Button is used 4,200 times across your organization. That is true. It is also dangerously incomplete.
What the dashboard cannot tell you: 600 of those instances override the padding token with raw pixel values. Another 200 wrap the component in a custom div to adjust layout behavior. Three separate teams have built their own button entirely — none of which appear in your adoption count. And the checkout team that said they planned to migrate to your new component library in Q2? They are still on the old version, three releases behind, and their build passes silently (Trueman, Design Systems Collective, 2026).
This is not a data problem. You have more numbers than most design system teams. This is an observability problem. The dashboard tracks adoption — whether something is used. It cannot answer the far more important question: how it is being used and where it is failing.
In production software engineering, this distinction was solved years ago. DevOps teams do not ask “is the API responding?” They ask “which endpoints are slow, which clients are hitting error rates, and what does the trace from login to checkout actually look like?” The discipline is called observability — the ability to understand a system’s internal state from its external outputs — and it is defined by three pillars: metrics (aggregated measurements), logs (event-level detail), and traces (a single request across every service it touches) (Trueman, DS Collective, 2026).
Design systems have never built this layer. Most teams cannot answer even the first-order questions about how their system behaves under real use. This article makes the case that they should — and that the tooling, the precedent, and the data already exist to do it today.
The Two Questions No Dashboard Answers
The standard design system dashboard shows: npm downloads per package, Figma library instance counts, adoption rate by team, number of components. These are monitoring metrics — they tell you whether something is up or down. They do not tell you why the system behaves the way it does.
Consider the questions that matter for a component in active development:
- Which props are being overridden most frequently, and what does that tell you about gaps in your API?
- Which design tokens are bypassed for raw color or spacing values, and by which teams?
- How many teams have built duplicate components that shadow yours?
- When a new version ships, who upgrades within the first sprint and who stays three major versions behind?
- Are there CSS overrides that accumulate silently, outside any component’s visibility?
A standard dashboard cannot answer a single one of these. Yet every one of these questions is answerable with the same tools that DevOps teams use for production systems.
The gap is structural, not technical. As Murphy Trueman put it, “we still think of design systems as a design practice that happens to involve code, rather than infrastructure that happens to involve design” (Trueman, DS Collective, 2026). That framing determines what you measure. When your system is a practice, you measure compliance — did teams follow the rules? When it is infrastructure, you measure health — is the system serving its consumers?
The difference matters because compliance metrics produce false negatives. A team that forked your Button and modified it internally looks compliant in your dashboard (no one deleted your component). A team that abandoned your system and built their own looks like a data gap (they never imported anything). Neither scenario surfaces as a problem until a manual audit months later.
What Agent Traces Reveal That Surveys Never Will
In early 2026, Murphy Trueman published a finding that reframes the entire observability conversation for design systems. Data that captures the gap between what developers want and what the system provides is already sitting on every engineer’s laptop — and it is being deleted on a 30-day timer (Trueman, “Agents Are the Most Honest Reviewers,” 2026).
AI coding agents — Claude Code, Codex, Cursor — write detailed session logs to ~/.claude/projects/ and ~/.codex/sessions/ as JSONL files. These logs contain every prompt, every tool call, every file read, every proposed diff, and every accepted or rejected edit. More importantly for design system teams, they capture the moments when an agent could not figure out how to use the system correctly.
Trueman identified four distinct signals from agent trace data that no survey or dashboard can capture:
Hallucinated props. An agent invents a prop that does not exist — <Button variant="tertiary-ghost"> — because the documentation left room for interpretation. The trace reveals not a user error but a hypothesis the agent formed about what your component should do. Every hallucinated prop is a documentation gap or an API-design gap wearing a user-error costume.
Bypassed tokens. An agent writes color: #3B82F6 instead of var(--color-interactive-primary). The trace shows the exact moment of semantic ambiguity: the agent could not determine whether the color was a brand value, an action indicator, or a hover state. The developer who would have known the difference is not in the loop because the agent made the decision independently.
Novel components. The agent generates a PromoBanner from scratch when CalloutBanner already exists in the design system. This is a discoverability failure, invisible to any adoption metric because the generated component has no import from the system. “The only record of the event is the trace” (Trueman, “Agents,” 2026).
Corrective turns. A human reviews the agent’s output and corrects it: “Use our Card component, not a div with a border.” Each correction is a labeled training example of what your documentation should have said. The pair — agent failure, human correction — is already tagged in the session log.
The practical implication is immediate and unsettling. Every [] Chat every agent session on your team’s laptops is generating a free design system audit. The logs capture intent — what the developer (or agent) wanted to build — not just what got used. Surveys collect mediated, polite feedback. Trace data shows unfiltered behavior under deadline pressure. And it is being auto-deleted after 30 days (Trueman, “Agents,” 2026).
The Daley team’s implementation provides the blueprint. They built an OpenTelemetry pipeline that runs a static code analysis scan via react-scanner daily in CI, emitting every component instance as an OTel span with attributes for component name, file path, CODEOWNER, props, and deprecation status. Each scan generates thousands of spans — they had to bump maxQueueSize to 10,000 to avoid data loss — but the result is a Honeycomb dashboard that shows, per team, which deprecated components are still in use, which props are trending up, and where migration effort is concentrated (Daley, January 2026).
The same pattern applies to agent traces. Grep ~/.claude/projects/ for hallucinated prop names, for raw color values that should be tokens, for component names that do not exist. Wire the results into the same OTel pipeline. The infrastructure is already built — the Daley implementation runs in a single GitHub Action with zero new headcount.
The Governance Framework That Makes Observability Actionable
Observability without governance is a dashboard that no one reads. The second half of the equation is the infrastructure to act on what the data reveals.
Adam Arant’s 2026 governance framework provides a practical seven-step playbook for design systems serving 10 or more consumer projects. The central insight: “A design system that serves one project is a component library. A design system that serves ten projects is an internal platform” (Arant, April 2026).
The framework integrates naturally with an observability pipeline:
Freeze the public API. One barrel file per package. Everything else is internal. An ESLint rule blocks deep imports at the consumer side. This single move converts 80% of accidental breakage into intentional breakage you can plan for. The shift from loose documentation to enforceable contracts mirrors the component-contract pattern documented in earlier design system research, where machine-readable API boundaries replace prose that teams may not read.
Ship codemods with every breaking change. “A breaking change without a migration path is a tax on every consumer” (Arant, 2026). The jscodeshift tool applied against the largest consumer first, then bundled into a CLI command. Automated migration changes the economics of breaking changes from “we cannot afford to break” to “we can refactor freely as long as the codemod follows.”
Track adoption with a manifest per consumer. A ds.manifest.json at each consumer project root records the design system version, components actually used, CSS override count, and last audit date. A nightly job aggregates manifests into a dashboard showing coverage, drift, and version distance per team.
Set deprecation timelines and enforce them. Six-month notice for low-traffic components, twelve months for high-traffic. Targeted reminders at 90, 30, and 7 days. Remove on the announced date. “Teams ask for extensions, and granting extensions teaches everyone that deadlines are negotiable. Do not” (Arant, 2026).
| Data Source | What It Answers | Blind Spot | Instrumentation Cost |
|---|---|---|---|
| Adoption dashboard | Is the component used? | How it is used, where it breaks | Zero (already running) |
| Agent trace grep | What did developers want that the system lacks? | Confirms intent vs. capability gap | 30 minutes to grep a week |
| OTel CI pipeline | Which instances override tokens or use deprecated components? | Intent behind the override | One GitHub Action, one free account |
| Consumer manifest (ds.manifest.json) | Which versions are in use, how many overrides exist? | Real-time drift between releases | One JSON file per consumer project |
| Corrective-turn log | Where did humans fix agent output? | Structural documentation gaps | Reading session logs once a week |
Arant’s framework and Daley’s OTel pipeline share a critical feature: they work together. The manifest provides the consumer-side data on version adoption and override counts. The OTel scan provides the usage-shape data — which props, which tokens, which overrides. The agent traces provide the intent data — what developers wanted but could not find. None of these sources alone gives a complete picture. Together, they form an observability stack that matches what application teams have had for years.
From Compliance to Health
The shift from monitoring to observability requires a mindset change that Murphy Trueman articulates cleanly: “The question isn’t whether teams are following your guidelines. The question is whether your system is healthy enough to serve their needs” (Trueman, “Stop Policing Your Design System,” 2026).
This reframing changes how you interpret violations. When a high-detachment rate appears on a component, it is not a compliance failure — it is a feature gap. When a team bypasses tokens for raw values, it is not a rules violation — it is a signal that your token scale lacks the values they need. “The question becomes ‘is the system healthy?’ instead of ‘did you follow the rules?’” (Trueman, “Stop Policing,” 2026).
The practical implications extend beyond team dynamics to resource allocation. A design system team with an observability pipeline can point to specific components, specific props, and specific teams with concrete data about where the system is failing. The budget conversation shifts from “we need more money for the design system” to “the Button component accounts for 34% of all token bypasses, and fixing it would reduce override-related bugs by an estimated 20 hours per sprint.” When you measure health instead of compliance, you argue with data instead of intuition — which is precisely the shift this earlier analysis of design system budget arguments calls for.
Three Moves for This Week
The path from monitoring to observability does not require a platform engineering team or a six-month migration. Three actions this week will produce more signal than most design system teams currently have:
1. Instrument one CI check. Run react-scanner with an OTel exporter. Start with one component — the most-used deprecated one. Emit spans for every instance. Point the exporter at a free Honeycomb or Grafana account. One afternoon, one dashboard, one data stream.
Do: Pick the component with the highest usage count on your current dashboard. If it is also the most overridden, you have found your observability wedge.
Do not: Wait until you can instrument every component. The first scan exposes the gap between dashboard numbers and real behavior. That gap is the argument for the second scan.
2. Define one SLO. Pick one measurable dimension of system health. “Fewer than 5% of Button instances use raw color values instead of token references” is a concrete, testable objective. Track it in the same dashboard. If you miss the target, you have a prioritized improvement item with a defined success criterion.
Do: Make it specific and measurable. “Button is healthy” is a sentiment. “Under 5% token bypass on Button” is a contract.
Do not: Define five SLOs on day one. One metric, one dashboard, one review per sprint. Expand when the data proves useful.
3. Read one week of agent traces. Ask every engineer on your team to grep their ~/.claude/projects/ directory for hallucinated props, bypassed tokens, and corrective turns from the past week. Aggregate the results in a shared document. The output will be the most honest, unfiltered list of your design system’s failure points you have ever seen (Trueman, “Agents,” 2026).
Do: Read the transcript of one session where the human corrected the agent. That pair — wrong choice, right correction — is a concrete documentation gap you can close.
Do not: Fix everything you find. Prioritize. The corrective turns that appear across three or more engineers are the structural failures. The one-off hallucination is likely an agent artifact.
The Dashboard Is Not Lying — It Is Just Incomplete
The problem with design system dashboards is not that the numbers are wrong. The 4,200 Button instances are real. The 85% adoption rate is real. The npm download count is real.
The problem is that these numbers answer a question no one is asking. Teams do not need to know whether a component is used. They need to know whether the component is working, whether consumers are fighting it, and whether the system as a whole is getting healthier or more brittle over time.
The infrastructure to answer those questions exists today. OpenTelemetry pipelines are standard in production engineering. Agent trace data is sitting on every developer’s machine. Governance frameworks with manifest tracking and codemod automation are documented and tested at organizations like Procore and athenahealth. The only missing piece is the decision to treat the design system as infrastructure worth observing — not a set of components worth counting.
The dashboard that reports 4,200 instances of Button is not lying. But every instance that overrode the padding token, every team that built their own, every corrective turn that an agent logged and a human corrected — those are the numbers that tell you what your system actually needs. And those numbers are waiting on hardware you already own.